This post is a deep dive into some of the software engineering work at Base Power. We’re *hiring*!
Picture this: It’s mid-2026. You own developer velocity at an economy-of-scale startup. Software engineers are the fixed cost around these parts, so the company gives them API keys for fancy coding agents. They are tasked with automating the processes that support the company’s geometric growth towards the minimum efficient scale required to color the balance sheet bright green. They need to ship yesterday.
Your colleagues learn the trick pretty fast: Parallel coding agents pushing, failing, fixing, and delivering stacks of pull requests (PRs) with passing continuous integration (CI) checks. The most combative submit north of 200 PRs a week.
Getting there is the easy part. If you sat through Christopher Nolan’s The Odyssey (with apologies for the 3,000-year-old spoilers if you haven’t), you know the rest of the story: the first act wraps up a ten-year war, and the getting-home takes the other two and a half hours. This is what happens to organizations that switch to agents: CI-passing PRs written at record speed, then hours or days getting reviewed and merged to production.
The pull request iteration loop
This was us at Base a month ago, so we rebuilt that path. This post is about how.
Step 1: Push your post-submit left
Let’s start with the obvious: no human comprehensively reviews 200 PRs a week. We use an array of AI review agents, which helps. Importantly, we also decided to shift as much of the review burden as possible into tests: we leaned into a monorepo and now aggressively test every atomic change before it merges, when feasible. More specifically, we made the uncommon choice to pull end-to-end suites that traditionally run post-merge, nightly, or before a release into the pre-merge CI gate. This way, a change gets in by surviving a well-designed test workload, not by being well-vetted.
Review burden versus testing burden
To be clear, we’d have argued against this before agents, but felt the calculus had flipped. Anyways, does this help?
Good news: Provided design discussions happen somewhere other than pull requests and the tests actually match your risk/reliability posture, this helps. Minor caveat: agents write the tests too, so a change could weaken its own gate. We trust reviewers to catch it if one does; test changes still require human attention. You’ll generally need a somewhat sophisticated set of change approval rules to protect your most precious lines of code.
Bad news: CI is now even slower! A PR or merge validation run can have a long wall-clock time, require an unreasonable number of machine-hours, or be inherently flaky (e.g., for tests that run on unreliable hardware). That cost is the villain of the rest of this post. Giving up the testing was off the table, because the testing is the only reason any of this is safe; the cost had to come down another way.
Step 2: Only run the tests you need, and save the footprint
This part isn’t exactly brain surgery: Don’t run the whole suite on every change, only the part the change can actually affect. At Base, we use an industry standard input- and content-addressed hermetic build system: Google’s Bazel, paired with Tinder’s bazel-diff. See this presentation if this is unfamiliar.
Affected build/test scopes: the footprint
footprint(PR,merge-base) = the affected leaves of the build graph.
Besides making pre-submit CI faster and cheaper, this produces a footprint of the PR, which turns out to matter: for a given change, a machine-computed answer to “what does this change touch relative to the reference point chosen by the CI run?”. Hold that thought, but for now: does this work?
Good news: Steps 1 and 2 fixed the left half of that first timeline. PRs now go green as fast as their affected tests go, cheaply, and with less of a human bottleneck.
Bad news: All that did for the right half is make it worse! Approved PRs now arrive by the hundreds, and every one of them still has to make its way to the same trunk branch. The bottleneck shifted right yet again, into the merge strategy.
Step 3: Hear the sirens’ song
This step isn’t really actionable; it’s more of an explainer to motivate what follows, in case you’re not clear about what merge queues are. Recall that a green checkmark is a statement about the past. Your PR was validated against the trunk branch of an hour ago, and thirty other PRs landed on the trunk branch since. Merging now means publishing a combination of changes that was never tested. Physical conflicts are caught by Git, but logical conflicts (two changes that each pass independently but break together) could slip through.
The stale green problem
So your trunk branch needs a guarantee: no combination of changes gets published without being validated first. There are plenty of fine implementations for serializing this validation, including GitHub's Merge Queue and GitLab's Merge Train. Unfortunately, this is slow at agent volume, even with diff-aware selective testing and caching:
- Once a PR triggers a heavy integration test suite, every PR following it pays the wall-time.
- Logical conflicts and flaky failures cause queue rejections; every PR that follows them has to restart its validation run.
Serial merge queue
- Long run / revalidating
- Merged
- Rejected or stale intersection
- Speculative
B runs concurrently, but its candidate contains A's changes: no cache hit, A's wall-time, A's rejection.
View the data as a table
| PR | Base | Footprint | Note |
|---|---|---|---|
| A | c₀ | {firmware} | — |
| B | c₀ | {billing} | inherits A's long run |
| C | c₀ | {firmware} | really does overlap A |
Note that this problem is mostly a consequence of step 1, which parked the heavy suites in front of the merge. This means that every engineer stuck in that line is hearing voices: Nothing that landed since has anything to do with your change. It’s fine. Just merge it..
No matter how appealing, better plug your ears and row, because every time a logical conflict lands, it blocks CI and treats the entire team to a front-row seat at the revert. So how do we solve it?
Step 4: Enter parallel merge queues
The line in step 3 is serial because the queue assumes every merge can affect every PR behind it. Step 2 says otherwise: each change carries a footprint. If two footprints are disjoint, neither change can invalidate the other’s green, so the PRs can commute. Give each its own lane and validate both concurrently - only changes whose footprints intersect need serialization. The queue tracks this with a ledger: the footprint of every merge it lands on the trunk branch. Intersect a PR’s footprint with the merges since its base, and you know exactly whose green went stale.
Parallel merge queue
- Long run / revalidating
- Merged
- Rejected or stale intersection
- Speculative
B no longer waits for A; it still rides a lane (candidate branch, CI dispatch, green report) to run nothing.
View the data as a table
| PR | Base | Footprint | ∩ since base |
|---|---|---|---|
| A | c₀ | {firmware} | {firmware} ← m₁ |
| B | c₀ | {billing} | ∅ |
| C | c₀ | {firmware} | {firmware} ← m₁ |
At Base, we evaluated trunk.io and Mergify, which both offer parallel merge queues with dynamically configured lanes. Uber’s SubmitQueue also caught our attention with its aggressively speculative approach, for which an open-source rewrite is in progress.
Any of those will fix it! The long run stops being everybody’s problem: B merges as soon as its own fully cached validation clears, and if A is rejected, it takes down its own candidate, not the whole line.
That being said.. B ran nothing and waited for a full-cache-hit CI run anyways. Why queue it at all?¹
Step 5: Directly merge to your trunk branch
Look at B’s row in the figure above. The intersection column already answered the only question that matters: nothing that landed since B’s base touches B’s footprint, so B’s green never went stale. And that answer cost one set intersection against the ledger. B’s lane (candidate branch, CI dispatch, a validation run made entirely of cache hits) re-derived a fact the queue already knew. When the intersection is empty, the safe move and the fast move are the same move: merge directly to main, no lane, no CI run. That optimization pushes us one notch further along the design space, without giving up correctness guarantees.
The decision rule is exactly the step 4 panel plus one column. For each green PR, intersect its footprint with everything the trunk branch has landed since its base and with everything currently validating in flight. Empty on both counts: merge directly, in seconds. Overlap with a landed merge: queue for revalidation in a lane, as before. A footprint that covers everything (a toolchain bump, say) serializes the world; that is the correct behavior, and it is rare². Depending on your software architecture, a large majority of your PRs may merge directly to main.
Parallel merge queue with direct-merge fast path
- Long run / revalidating
- Merged
- Rejected or stale intersection
- Speculative
B’s empty intersection lets it merge straight to the trunk branch and its footprint is appended to the ledger; only the overlapping firmware PRs pay for a lane.
View the data as a table
| PR | Base | Footprint | ∩ since base |
|---|---|---|---|
| A | c₀ | {firmware} | {firmware} ← m₁ |
| B | c₀ | {billing} | ∅ |
| C | c₀ | {firmware} | {firmware} ← m₁ |
We didn’t set out to build this; nobody wants to own a merge queue. But nobody sold the fast path either: a queue that uses the attested footprint to answer “must we test again?” and skips validation when the answer is no. Our current situation (about 100 people, agents everywhere, heavy integration tests) wanted it, so we built it³. It took an engineer about three weeks: two weeks from start to rollout, and another week of iterating on it in production towards stability and performance.
What we built is deliberately small: one Go service, about 16,000 lines plus a React dashboard and Postgres for state. A validation run is ordinary CI: push a candidate branch, dispatch the same workflow PRs run, squash-merge on green, record the footprint in the ledger. Overlapping PRs ride merge trains (the queued PR tree in the dashboard above), so even the slow path extracts parallelism.
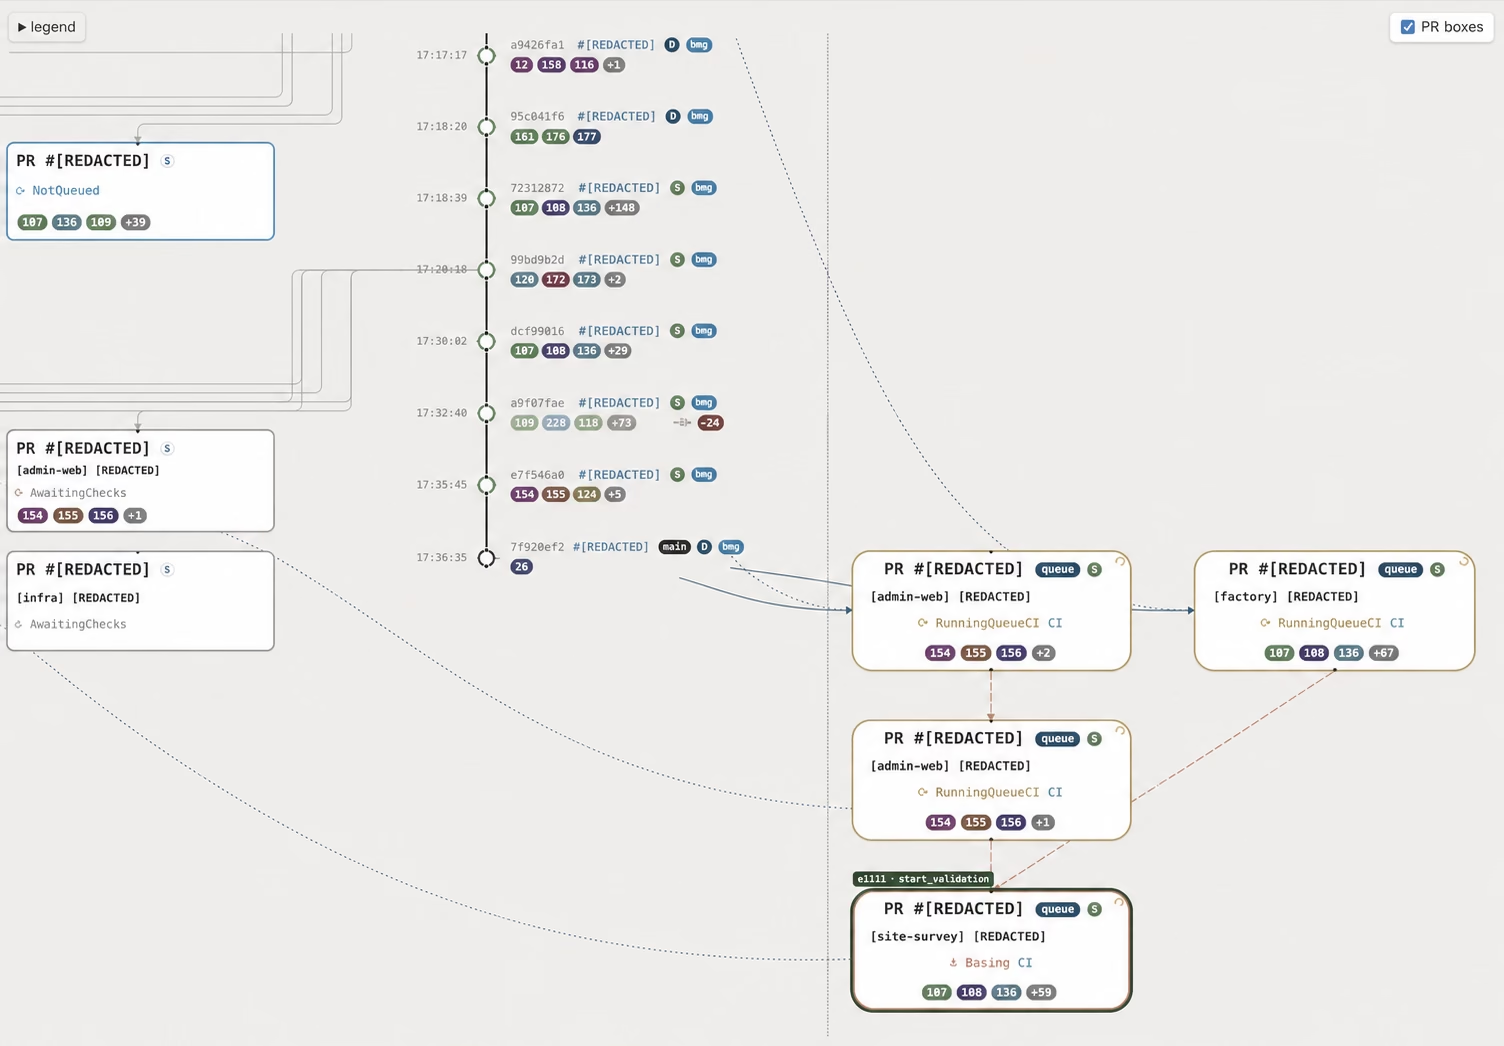
A merge queue is concurrent, stateful, and guards your trunk branch, so we tested it like infrastructure. The whole system (real executor, real Postgres, fake GitHub) runs in-process, so every bug becomes a reproducible test case: overlap chains, merge trains, red builds, pushes mid-validation, footprint drift, external merges, and crashes injected at arbitrary points. Alongside those sits an exhaustively enumerated corpus of about 80,000 deterministic cases sweeping entry counts, footprint assignments, and train depths. On top of that sits model-based fuzzing: random multi-actor traffic (authors, CI, operators, a chaos actor) with global properties asserted after every command. The timing mattered, too: this work coincided with the release of Fable-class models⁴, which we exclusively used. In our estimate, the ROI of an internal build would not have been favorable before this model tier. This overall approach resulted in an order of magnitude drop of our median time-to-trunk, which supported our contribution volume more than doubling since March. 40% of our merges skip validation entirely, and in our estimates, build graph improvements (tighter footprints, fewer over-broad targets) will take that north of 70%.
About the Author
Valentin Reis works on software infrastructure at Base Power. Previously, he worked on HPC systems at Argonne National Laboratory and helped build the software stack for Groq’s inference accelerator.
We just raised a Series D and are hiring for software roles. If you are interested in building fundamentals-driven solutions for a high growth vertical, click below.
Notes
- At the time of writing, the vendors we had evaluated did not offer this optimization.
- Another trick is relying on GitHub’s or GitLab’s auto-rebase-on-main behavior, which rebases branches when starting CI workflows. This makes CI runs closer to your trunk’s HEAD, which increases the probability of direct merges.
- Since we did this work, Mergify and trunk.io have shipped this direct-merge optimization. Check them out!
- Protip: If you’d like to know which models perform best on any given day, take a peek at the Is It Just Me? newsletter, also proudly made in Austin, TX!